@pasarus/pi-vertex2.1.4
Google Vertex AI provider for Pi coding agent with dynamic model discovery
Untested on omp
This is a pi package. No one has reported whether it works on omp yet. If you try it, add your result below.
Reports 0
No reports yet.
Readme
pi-vertex


A Google Vertex AI provider for the Pi Coding Agent — Gemini, Claude, Llama, DeepSeek, Qwen, Mistral and the rest of the Vertex Model Garden behind a single provider, billed through your GCP project, with dynamic model discovery so models that are enabled in your project show up in the selector without a code change or a release.
pi install npm:@pasarus/pi-vertex
export GOOGLE_CLOUD_PROJECT=your-project-id
export GOOGLE_APPLICATION_CREDENTIALS=/path/to/key.json   # or: gcloud auth application-default login
About this fork
Lineage:
ssweens/pi-packages— original@ssweens/pi-vertex, published inside a mono-repolhl/pi-vertex—git filter-repoextraction into a standalone repo with tests, lint and CI (@lhl/pi-vertex, v1.1.5 → v1.1.9)cebarks/pi-vertex— added dynamic model discovery via Model Garden API (@cebarks/pi-vertex, v2.0 → v2.1.2)- this repo —
Pasarus/pi-vertex(@pasarus/pi-vertex, v2.1.3+)
What this fork adds (v2.1.3)
| Change | Details |
|---|---|
| Adaptive thinking fixes | Fully supports Claude 4.6+, 4.7+, 4.8, 5+ adaptive thinking using { type: "adaptive", display: "summarized" } and output_config: { effort }. Eliminates the thinking.type.enabled is not supported for this model 400 error. Restores visible thinking text via display: "summarized". |
| Tool-use thinking block preservation | Preserves thinking blocks with thought signatures across multi-turn tool replay even when thinking text is empty, preventing Anthropic 400 thinking blocks cannot be modified errors. |
| Gemini 3 tool call IDs | Correlates tool calls and responses using id on functionCall and functionResponse for Gemini 3+ models (requiresToolCallId). |
| Tool schema sanitization | Strips $schema, $id, and other meta-declarations from tool definitions, preventing 400 invalid schema errors on both Anthropic and Gemini endpoints. |
| Multimodal tool results | Replays images inside tool results for Claude and Gemini, enabling vision tool workflows. |
| Redacted thinking support | Properly maps redacted_thinking blocks back to Anthropic. |
Dynamic model discovery (v2.x)
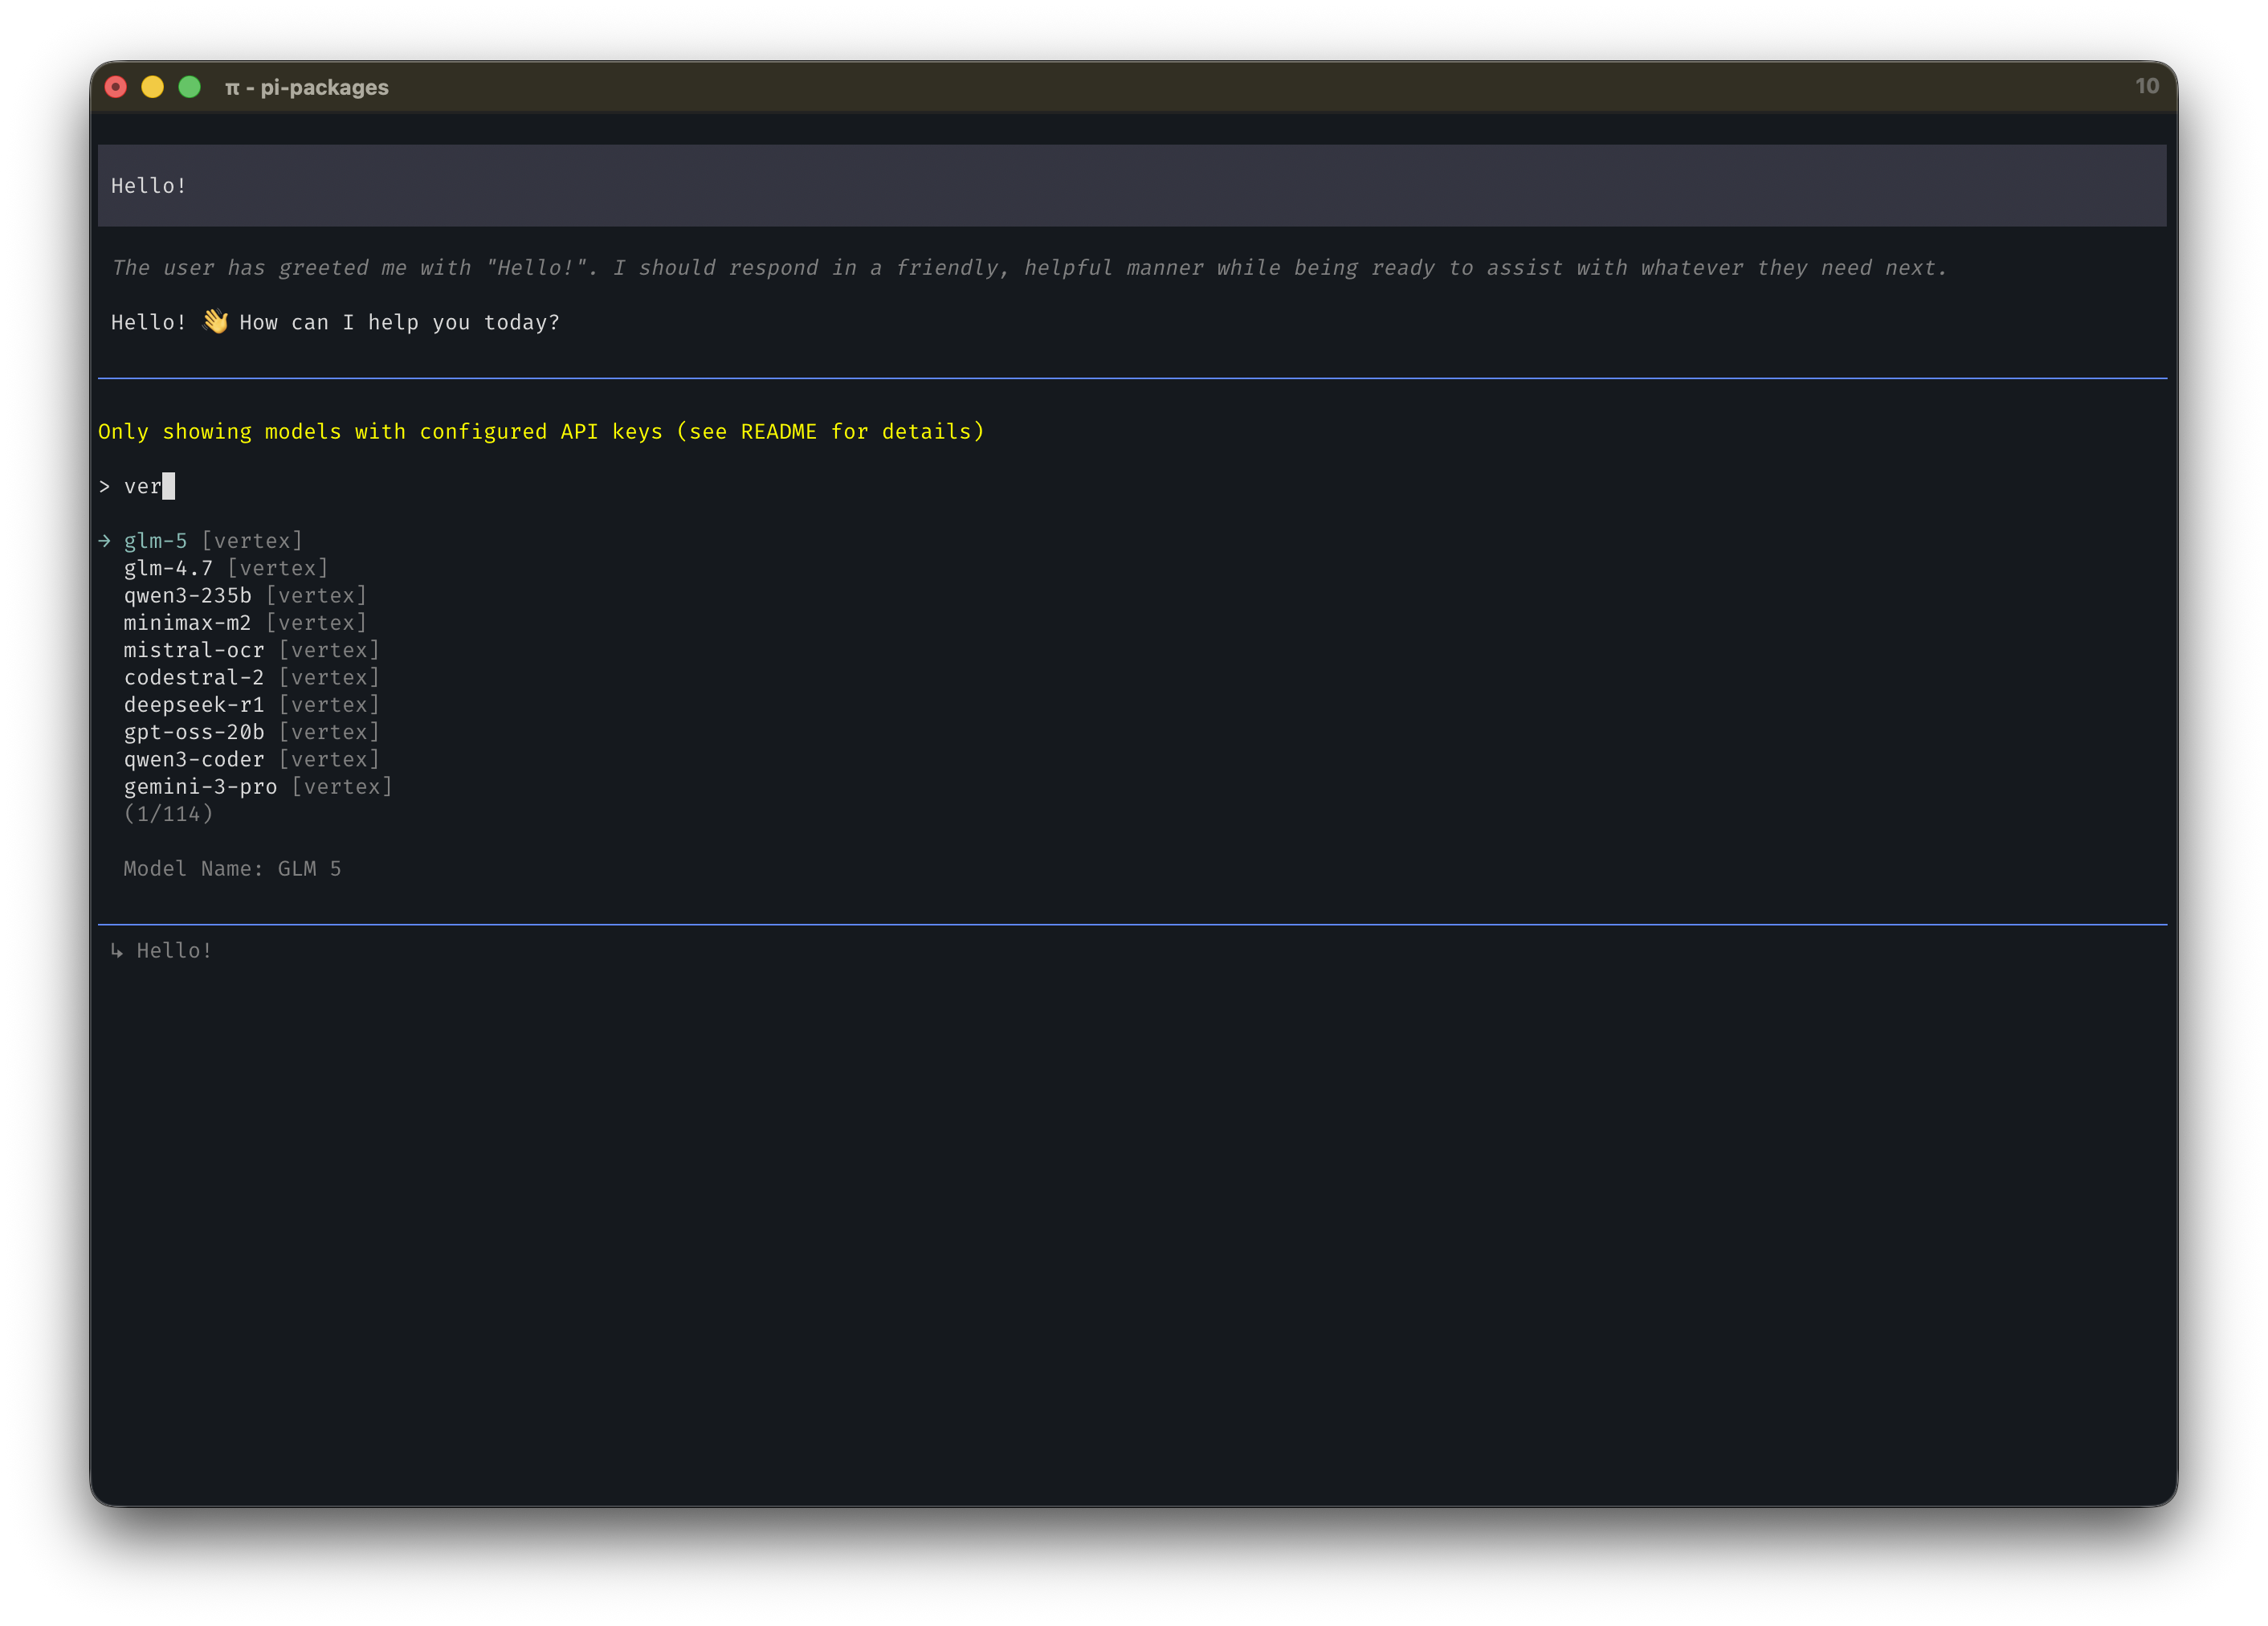
The extension queries the Model Garden API at startup, probes each model for project-level access, and registers what actually answers:
| Feature | Details |
|---|---|
| Dynamic model discovery | discovery.ts lists publishers/{p}/models (v1beta1) for 11 publishers, filters non-chat models (TTS, embeddings, Imagen), and registers the survivors — new models appear with no code change |
| Probe-based availability | Each candidate is checked with a countTokens request against your project. 200 → available; 400 "…infeasible" → available (Claude/MaaS don't implement countTokens); 404/org-policy/not-servable → skipped. No more offering models your project can't reach |
Disk cache + /vertex-refresh |
Results cached to ~/.pi/agent/cache/pi-vertex-models.json (default TTL 24 h) so startup stays fast; /vertex-refresh clears the cache and re-probes in-session |
| Discovery configuration | discoveryEnabled, discoveryCacheTtlMs, discoveryPublishers in the settings file; falls back to the full static table if discovery is off or fails |
| New models | claude-opus-4-8, claude-sonnet-5 |
| pi package scope migration | Moved to @earendil-works/pi-ai / @earendil-works/pi-coding-agent |
Provenance
- Fork point:
@cebarks/pi-vertexv2.1.2 - npm:
@pasarus/pi-vertex· repo:Pasarus/pi-vertex - Requirements: pi ≥ 0.74 (the
@earendil-works/*scope); developed against 0.84.x
Model discovery
At startup the extension runs four phases, then registers the provider once:
- List — one
GET /v1beta1/publishers/{publisher}/models?pageSize=100per publisher (5 s timeout each, all in parallel). Publishers:anthropic,google,meta,mistralai,deepseek-ai,xai,qwen,moonshotai,minimaxai,openai,zai-org. - Filter — drop IDs matching
-tts,-embedding,-imagen,textembedding,-native-audio,-image. - Probe — a
countTokensrequest per candidate, 8 workers, 5 s timeout each. Probing uses each publisher's serving region (us-east5for Anthropic,globalfor Google,us-central1for the rest), which is only an availability check — it does not change the endpoint your requests go to. - Enrich — models present in the static tables keep their real pricing, context window and capability flags; models discovered but not described statically get publisher defaults (below) and show up with a generated display name.
The result is cached as JSON on disk and reused until the TTL expires, so the probe cost is paid once per day. The startup widget reports the count and whether it came from cache:
[pi-vertex] Project: my-gcp-project | 48 models available (cached)
Defaults for models that aren't in the static tables (_default catches any publisher not listed):
| Publisher | Endpoint | Context | Max output | Input | Reasoning | Probe region |
|---|---|---|---|---|---|---|
anthropic |
maas | 200K | 64,000 | text, image | yes | us-east5 |
google |
gemini | 1M | 65,535 | text, image | yes | global |
meta |
maas | 128K | 32,000 | text | yes | us-central1 |
mistralai |
maas | 128K | 32,000 | text | no | us-central1 |
deepseek-ai |
maas | 160K | 32,000 | text | yes | us-central1 |
xai |
maas | 200K | 32,000 | text, image | yes | us-central1 |
others (_default) |
maas | 128K | 32,000 | text | yes | us-central1 |
Because defaults include placeholder pricing, costs shown in pi for an unknown model are approximate until you add it to the static tables — that's a deliberate trade-off: surfacing a model beats hiding it, and a one-line PR to models/maas.ts makes it exact.
Features
- 49 statically described models across Gemini (9), Claude (16), Llama (3) and other MaaS (21) — plus whatever else discovery finds in your project
- Unified streaming through one provider: Gemini via
@google/genai, Claude via the native@anthropic-ai/vertex-sdk, everything else via Vertex's OpenAI-compatible endpoint - Full tool calling with dual-format transcript extraction (
resolveContextTools&resolveSystemPrompt), multimodal image results, and Gemini 3 tool call IDs - Thinking / reasoning: Gemini 3 thinking levels, Gemini 2.5 thinking budgets, thought-signature preservation, Claude adaptive (
display: "summarized") and legacy thinking formats - Automatic auth via Application Default Credentials or a service-account key
- Region awareness: global endpoints by default, regional when required, with regional Claude pricing applied automatically
- Cost tracking for all statically known models, including cache reads/writes and thinking tokens
Installation
# Via pi (recommended)
pi install npm:@pasarus/pi-vertex

# Or via npm
npm install -g @pasarus/pi-vertex

# Or from source
git clone https://github.com/Pasarus/pi-vertex.git
cd pi-vertex && npm install
pi install /path/to/pi-vertex
Setup
1. Authenticate with Google Cloud
# Option A: user credentials (development)
gcloud auth application-default login

# Option B: service account (production)
export GOOGLE_APPLICATION_CREDENTIALS=/path/to/service-account-key.json
The project also needs the Vertex AI API enabled (gcloud services enable aiplatform.googleapis.com), and any model you want must be enabled for the project — that's exactly what discovery probes for.
2. Environment variables
export GOOGLE_CLOUD_PROJECT=your-project-id    # required (GCLOUD_PROJECT also accepted)
export GOOGLE_CLOUD_LOCATION=us-central1       # optional: override the per-model region
3. Configuration file (optional)
~/.pi/agent/settings/pi-vertex.json — every field is optional, and file values take priority over environment variables:
{
  "googleCloudProject": "my-gcp-project",
  "googleCloudLocation": "us-central1",
  "googleApplicationCredentials": "/path/to/service-account.json",
  "discoveryEnabled": true,
  "discoveryCacheTtlMs": 86400000,
  "discoveryPublishers": ["anthropic", "google", "meta"]
}
| Key | Default | Effect |
|---|---|---|
discoveryEnabled |
true |
false registers the 45 static models only — no network calls at startup |
discoveryCacheTtlMs |
86400000 (24 h) |
Cache lifetime; 0 forces a fresh probe every start |
discoveryPublishers |
all 11 | Narrow the publisher set to cut startup probe time |
4. Verify
pi --provider vertex --model gemini-2.5-pro --version
Usage
pi --provider vertex --model claude-opus-4-8
pi --provider vertex --model gemini-3.1-pro
pi --provider vertex --model llama-4-maverick
pi --provider vertex --model deepseek-v3.2
pi --provider vertex --model claude-sonnet-4-6 --reasoning high
Within a session, /vertex-refresh clears the cache, re-probes, and reports what is now available:
/vertex-refresh
→ Vertex model cache refreshed. 48 models available: claude-opus-4-8, gemini-3.5-flash, …
Shell aliases keep the typing down — note pi's --provider vertex plus a model id, so one alias per model you actually use:
alias pic='GOOGLE_CLOUD_PROJECT=my-project pi --provider vertex --model claude-opus-4-8'
alias pig='GOOGLE_CLOUD_PROJECT=my-project pi --provider vertex --model gemini-3.5-flash'
Model reference
Static metadata; discovery may register additional models, and may omit ones listed here if your project has no access. Prices are USD per 1M tokens on the global endpoint unless noted.
Gemini
| Model | Context | Max output | Input | Reasoning | Price (in/out) | Cache read |
|---|---|---|---|---|---|---|
gemini-3.5-flash |
1M | 65,535 | text, image | yes | $1.50/$9.00 | $0.15 |
gemini-3.1-pro |
1M | 65,535 | text, image | yes | $2.00/$12.00 | $0.20 |
gemini-3.1-flash-lite |
1M | 65,535 | text, image | yes | $0.25/$1.50 | $0.025 |
gemini-3-flash |
1M | 65,535 | text, image | yes | $0.50/$3.00 | $0.05 |
gemini-2.5-pro |
1M | 65,535 | text, image | yes | $1.25/$10.00 | $0.125 |
gemini-2.5-flash |
1M | 65,535 | text, image | yes | $0.30/$2.50 | $0.03 |
gemini-2.5-flash-lite |
1M | 65,535 | text, image | yes | $0.10/$0.40 | $0.01 |
gemini-2.0-flash |
1M | 8,192 | text, image | no | $0.15/$0.60 | $0 |
gemini-2.0-flash-lite |
1M | 8,192 | text, image | no | $0.075/$0.30 | $0 |
Claude
Non-global regions use costRegional where Google publishes a regional premium.
| Model | Context | Max output | Reasoning | Global (in/out) | Regional (in/out) |
|---|---|---|---|---|---|
claude-opus-5-5 |
1M | 128,000 | yes | $5.00/$25.00 | $5.50/$27.50 |
claude-opus-5 |
1M | 128,000 | yes | $5.00/$25.00 | $5.50/$27.50 |
claude-sonnet-5 |
1M | 128,000 | yes | $2.00/$10.00 | $2.20/$11.00 |
claude-fable-5-1 |
1M | 128,000 | yes | $10.00/$50.00 | $11.00/$55.00 |
claude-fable-5 |
1M | 128,000 | yes | $10.00/$50.00 | $11.00/$55.00 |
claude-opus-4-8 |
1M | 128,000 | yes | $5.00/$25.00 | $5.50/$27.50 |
claude-opus-4-7 |
1M | 128,000 | yes | $5.00/$25.00 | $5.50/$27.50 |
claude-opus-4-6 |
1M | 128,000 | yes | $5.00/$25.00 | $5.50/$27.50 |
claude-sonnet-4-6 |
1M | 128,000 | yes | $3.00/$15.00 | $3.30/$16.50 |
claude-opus-4-5 |
200K | 32,000 | yes | $5.00/$25.00 | $5.50/$27.50 |
claude-sonnet-4-5 |
200K | 64,000 | yes | $3.00/$15.00 | $3.30/$16.50 |
claude-haiku-4-5 |
200K | 64,000 | yes | $1.00/$5.00 | $1.10/$5.50 |
claude-opus-4-1 |
200K | 32,000 | yes | $15.00/$75.00 | uniform |
claude-opus-4 |
200K | 32,000 | yes | $15.00/$75.00 | uniform |
claude-sonnet-4 |
200K | 64,000 | yes | $3.00/$15.00 | uniform |
claude-3-5-sonnet-v2 |
200K | 8,192 | no | $3.00/$15.00 | uniform |
Llama
| Model | Context | Max output | Reasoning | Price (in/out) |
|---|---|---|---|---|
llama-4-maverick |
512K | 32,000 | yes | $0.35/$1.15 |
llama-4-scout |
1.25M | 32,000 | yes | $0.25/$0.70 |
llama-3.3-70b |
128K | 8,192 | no | $0.72/$0.72 |
Other MaaS
| Model | Publisher | Context | Max output | Reasoning | Price (in/out) |
|---|---|---|---|---|---|
grok-4.20-reasoning |
xai | 200K | 32,000 | yes | $1.25/$2.50 |
grok-4.1-fast-reasoning |
xai | 128K | 32,000 | yes | $0.20/$0.50 |
gemma-4-26b-a4b-it |
256K | 128,000 | no | $0.15/$0.60 | |
mistral-medium-3 |
mistralai | 128K | 32,000 | no | $0.40/$2.00 |
mistral-small-3.1 |
mistralai | 128K | 32,000 | no | $0.10/$0.30 |
codestral-2 |
mistralai | 256K | 32,000 | no | $0.30/$0.90 |
mistral-ocr |
mistralai | 128K | 32,000 | no | $0.0005 (per page) |
deepseek-v3.2 |
deepseek-ai | 160K | 32,000 | yes | $0.56/$1.68 |
deepseek-v3.1 |
deepseek-ai | 160K | 32,000 | yes | $0.60/$1.70 |
deepseek-r1 |
deepseek-ai | 160K | 32,000 | yes | $1.35/$5.40 |
deepseek-ocr |
deepseek-ai | 160K | 32,000 | no | $0.30/$1.20 |
qwen3-235b |
qwen | 256K | 32,000 | yes | $0.22/$0.88 |
qwen3-next-instruct |
qwen | 256K | 32,000 | yes | $0.15/$1.20 |
qwen3-next-thinking |
qwen | 256K | 32,000 | yes | $0.15/$1.20 |
qwen3-coder |
qwen | 256K | 32,000 | yes | $0.22/$1.80 |
gpt-oss-120b |
openai | 128K | 32,000 | yes | $0.09/$0.36 |
gpt-oss-20b |
openai | 128K | 32,000 | no | $0.07/$0.25 |
kimi-k2-thinking |
moonshotai | 256K | 32,000 | yes | $0.60/$2.50 |
minimax-m2 |
minimaxai | 192K | 32,000 | yes | $0.30/$1.20 |
glm-5 |
zai-org | 200K | 32,000 | yes | $1.00/$3.20 |
glm-4.7 |
zai-org | 200K | 32,000 | yes | $0.60/$2.20 |
mistral-ocr is billed per page ($0.0005/page on both sides) rather than per token; the two *-ocr models do not support tool calling.
Endpoints and regions
Every static model defaults to region: "global", which resolves to https://aiplatform.googleapis.com/v1/projects/{project}/locations/global/.... A regional endpoint looks like https://{location}-aiplatform.googleapis.com/v1/projects/{project}/locations/{location}/....
GOOGLE_CLOUD_LOCATION (or googleCloudLocation) is a global override applied on top of each model's own region — setting it forces every request through that region, including for models that only serve from global. Use it when you have a data-residency requirement and have confirmed the models you rely on are servable there; it also switches Claude pricing to costRegional when a premium is defined.
Developer and Agent Guide
See AGENTS.md for detailed architecture documentation, model dispatch invariants, transcript tool extraction details, and contribution instructions.
Architecture
                         ┌─────────────┐
                         │     Pi      │
                         └──────┬──────┘
      registerProvider("vertex")│  /vertex-refresh
                                ▼
   ┌────────────────────────────────────────────────┐
   │                   pi-vertex                    │
   │                                                │
   │  config.ts ─ settings/pi-vertex.json           │
   │  auth.ts ───── ADC / service account, project, │
   │                location, endpoint builder      │
   │  discovery.ts ─ Model Garden list ──┐          │
   │                  countTokens probe ─┤ cache    │
   │                                     ▼          │
   │  models/ ─ static metadata ═══► merged model set (45+ registered)
   └────────────────────────────────┬───────────────┘
                                streamVertex()
                                     │ endpointType
                    ┌────────────────┴────────────────┐
                    ▼                                 ▼
        ┌───────────────────────┐        ┌──────────────────────────┐
        │  gemini (@google/genai)│        │ maas (OpenAI-compat) or  │
        │                        │        │ Claude (vertex-sdk)      │
        └───────────────────────┘        └──────────────────────────┘
Development
npm ci
npm run build         # tsc --noEmit
npm run check         # biome check
npm test              # vitest run
npm run test:coverage
The GitHub Actions workflow (.github/workflows/ci.yml) runs build + check in one job and test:coverage (with a coverage artifact) in another, on every push and PR touching main.
Two conventions worth knowing if you touch this code:
tests/auth.test.tsrebuildsprocess.envfrom a baseline withGOOGLE_CLOUD_PROJECT,GCLOUD_PROJECT,GOOGLE_CLOUD_LOCATION,CLOUD_ML_REGIONandGOOGLE_APPLICATION_CREDENTIALSstripped. Every assertion there is about fallback order, so an ambient value exported by your shell would outrank the fixture and silently invert the test. Keep new auth assertions inside that baseline.biome.jsondisables the formatter forpackage.json: npm rewrites that file on everynpm version/ dependency change, expanding short arrays back onto separate lines, which biome then flags. Same reasoning fortests/**andstreaming/maas.ts, wherenoExplicitAnyis off (mock objects, and the Anthropic normalize/replay pipeline — see the note at the top of that file).
Dependencies
@google/genai— Gemini generateContent streaming@anthropic-ai/vertex-sdk— native Claude-on-Vertex streaminggoogle-auth-library— ADC/service-account tokens@earendil-works/pi-ai,@earendil-works/pi-coding-agent— peer dependencies (provided by pi)
License
MIT — see LICENSE. Copyright for the original work is held by ssweens; this fork preserves the upstream notice and full commit history.