pi-prompt-suggestion0.1.2
Predicts your next message after each turn and shows it as ghost text in pi's input box (Tab to accept)
Untested on omp
This is a pi package. No one has reported whether it works on omp yet. If you try it, add your result below.
Reports 0
No reports yet.
Readme
pi-prompt-suggestion
English | 中文
A pi extension that predicts your next message and shows it as dimmed ghost text in the empty input box.
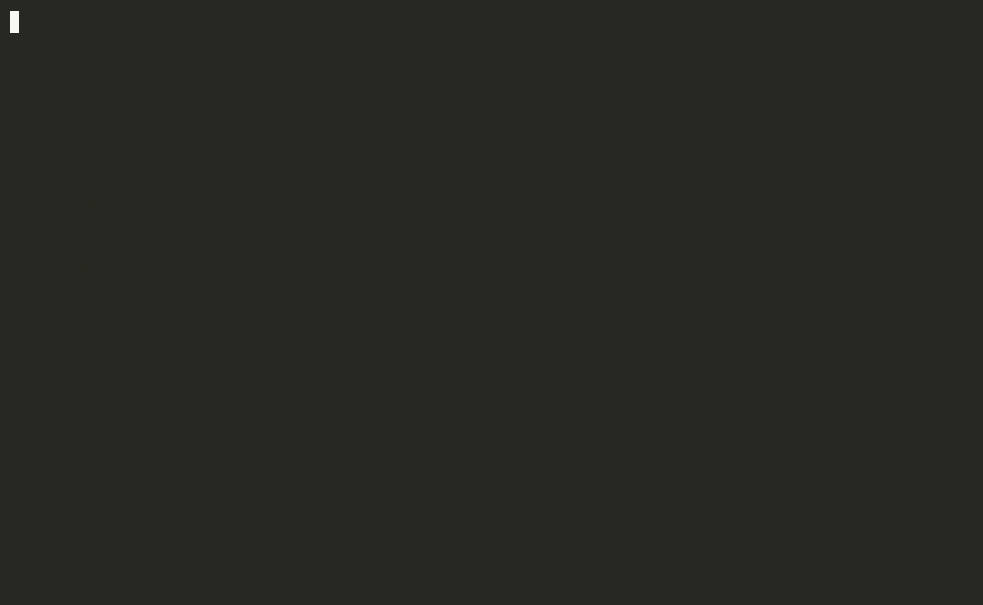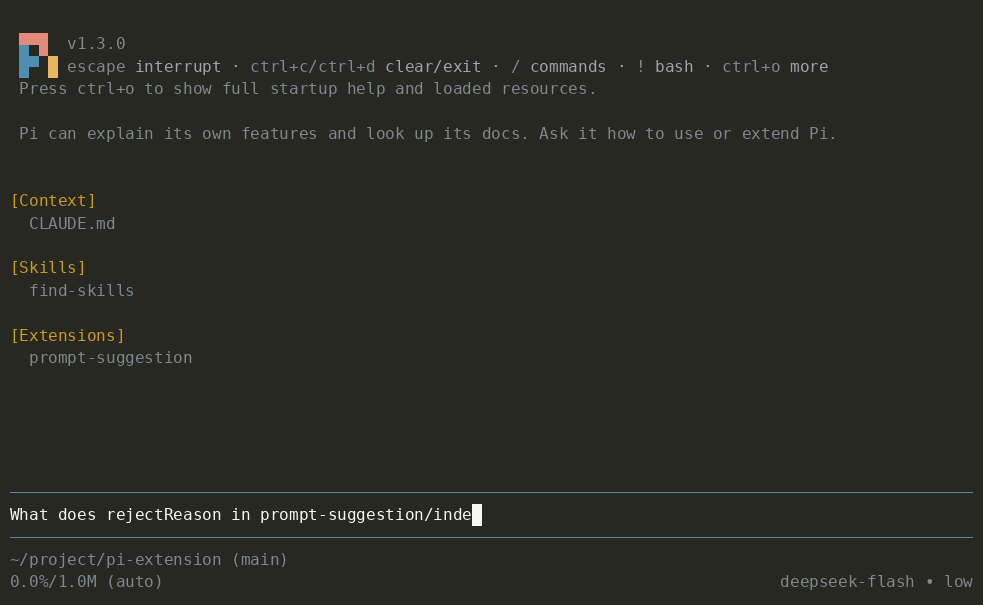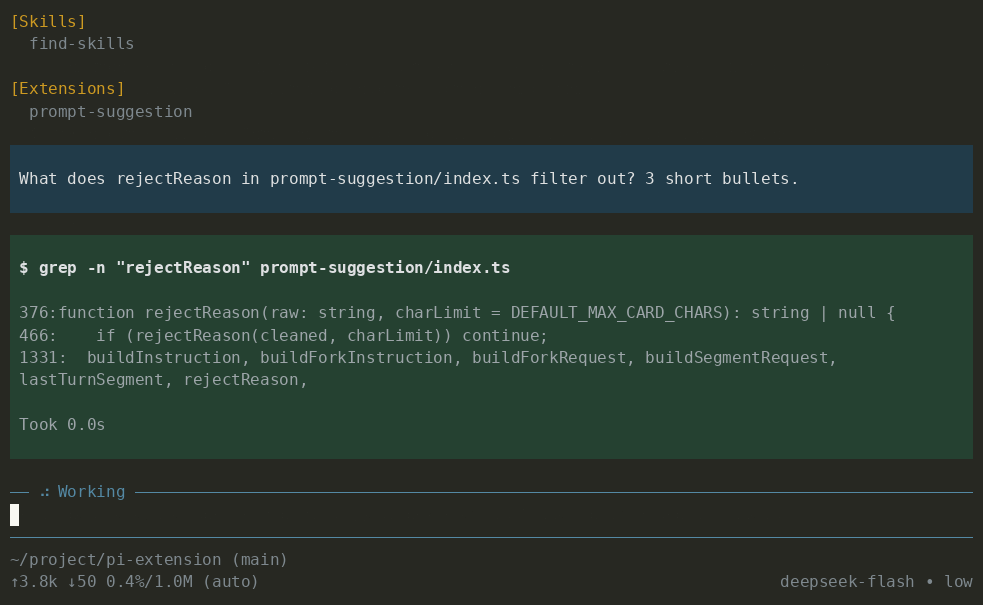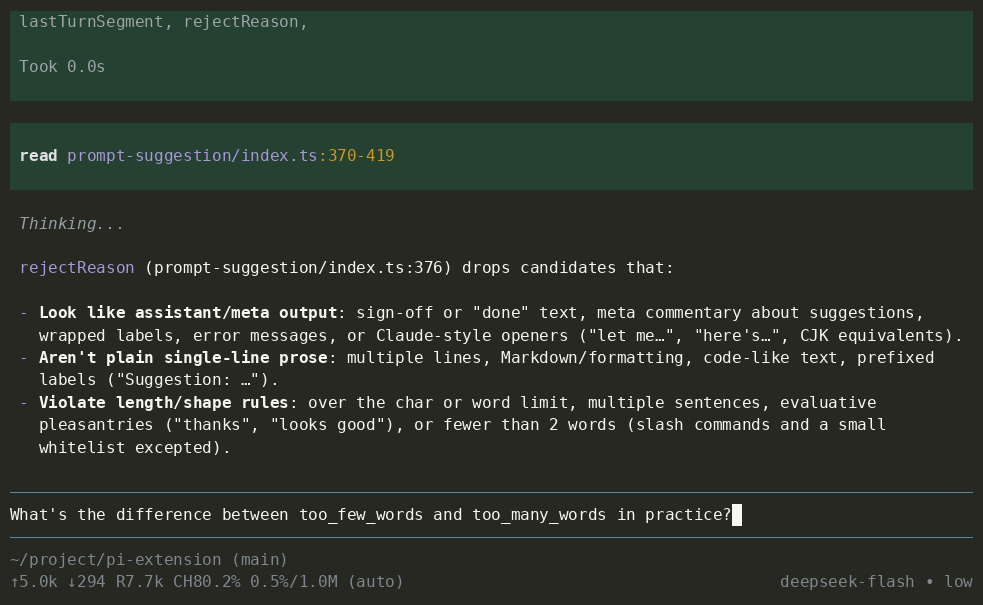
- Press Tab in an empty input box to get a suggestion; press Tab again to accept it, Esc to dismiss it.
- Typing hides it; clearing the input box brings it back. Sending a message or starting a new turn discards it.
- Optional: set an Idle delay to get suggestions automatically once a turn ends and the input box has been idle that long (off by default).
Highlights
- Predicts what you would say, not what the assistant would. The prompt and output rules follow Claude Code's prompt-suggestion feature: a suggestion is the next thing you would type yourself, not an assistant-voice offer.
- Silent rather than wrong. Model output goes through a deterministic filter that rejects evaluations ("looks good", "thanks"), assistant-voice text, Markdown, code, multiple sentences, and anything too long. When there is no good guess, nothing is shown.
- Reuses the session's prompt cache. In fork mode the request is identical to the main loop's (same thinking level, tools, and parameters), so it hits the session's own cache: 99.9% cache hits measured on a long session, so even a full-context request costs little more than cache reads. While the cache is cold or expired, the cheap segment mode is used instead (with the segment model you configured), and fork resumes as soon as the conversation warms the cache again.
- Speaks your language. Chinese conversations get Chinese suggestions; the filter also catches CJK pleasantries and assistant voice.
- Plays well with other editor extensions. It wraps the current input editor instead of replacing it, so it works alongside extensions that install their own editor (such as
pi-powerline-footer). If it can't draw inside the editor, it shows a line above it instead. - Works out of the box. Fork mode with the session's model is the default, so no setup is needed; every setting is in
/suggestionand applies immediately. - Lightweight. A single file with no dependencies beyond pi itself.
Install
The extension is published to npm. Install it with pi's package manager:
pi install npm:pi-prompt-suggestion
This adds it to packages in ~/.pi/agent/settings.json, so it loads in every session. Restart pi (or run /reload) to activate it; it works with no setup.
pi install -l npm:pi-prompt-suggestion  # this project only (.pi/settings.json)
pi -e npm:pi-prompt-suggestion          # try it for one session without installing
pi update npm:pi-prompt-suggestion      # update to the latest version
pi remove npm:pi-prompt-suggestion      # uninstall
Usage
After the assistant replies, press Tab in the empty input box; the predicted message appears as dimmed text. To get suggestions without pressing Tab, set Idle delay in /suggestion (they then start after the second assistant reply).
| Key | Action |
|---|---|
| Tab (empty box, nothing shown) | Generate a suggestion (gives its best guess even when the next step is unclear) |
| Tab (suggestion shown) | Accept: puts the text in the input box (press Enter to send, or edit it first) |
| Esc | Dismiss |
| Any other key | Type normally; the suggestion comes back if you clear the box |
How it generates
Pick the mode with /suggestion → Context mode:
- fork (default): replays the full session with the session's model, so the request reuses the session's own prompt cache, which gives the best suggestions at low cost when the cache is warm. Fork falls back to segment (using the segment model, if one is configured) when the model doesn't return a usable answer. While the cache looks cold or expired (including right after you switch models or change the thinking level, since the cache no longer matches), segment is used instead; fork resumes automatically once you keep talking and a new turn warms the cache. If forks keep missing the cache, fork is turned off for the rest of the session; a new session or
/reloadturns it back on. - segment: sends a short excerpt of the last turn to the segment model. Cheap and fast. Requires a model under Segment model; without one, segment mode generates nothing.
Pick a Segment model (for example a cheap, fast model) if you also want suggestions while the cache is cold or expired. Without one, fork has no fallback and no suggestion is shown at those times.
Settings
Run /suggestion to open the settings screen. Settings are stored in ~/.pi/agent/prompt-suggestion.json (or under PI_CODING_AGENT_DIR) and take effect immediately.
| Setting | Default | Description |
|---|---|---|
| Context mode | fork | fork (session model, reuses the prompt cache) or segment (segment model, short excerpt) |
| Segment model | Not set | Model for segment requests, including fork's fallback. Not set: no segment requests. Fork always uses the session model |
| Tab to generate | on | Tab in an empty input box generates immediately |
| Idle delay | off | Generate automatically once the input box has been idle this long after a turn; off (0): only on Tab |
| Max length | 50 chars | Longer suggestions are discarded |
| Cache freshness | 300s | Older replies are treated as an expired cache (segment is used until the next turn warms it) |
| Fork context limit | unlimited | Skip fork above this many tokens |
| Diagnostic log | off | Write one JSONL line per generation to ~/.pi/agent/prompt-suggestion.log |
PI_SUGGESTION_LOG=<path> also enables the diagnostic log.
Cost
Each suggestion is one extra model request. In fork mode (the default) it is a full-context request that is mostly cache reads, since it only runs while the cache is warm; in segment mode it is a small request. Nothing is sent unless you press Tab or set an Idle delay; turning Tab to generate off as well stops all requests.
License
MIT